# paddleocr-text-recognition

Adopt this skill: https://proskills.md/skills/other/paddlepaddle-paddleocr-skills-paddleocr-text-recognition

Page: https://proskills.md/skills/other/paddlepaddle-paddleocr-skills-paddleocr-text-recognition
This document is the public skill bundle for that page. It contains SKILL.md and every helper file the catalog carries. No login is required.

## File: skills/paddleocr-text-recognition/SKILL.md
size: 3726
upstream: https://github.com/paddlepaddle/paddleocr/blob/HEAD/skills/paddleocr-text-recognition/SKILL.md

````text
---
name: paddleocr-text-recognition
description: >-
  Use this skill whenever the user wants text extracted from images, photos, scans, screenshots,
  or scanned PDFs. Returns exact machine-readable strings with line-level text and optional bbox
  coordinates. Strong accuracy for CJK, small print, and handwritten text.
  Trigger terms: OCR, 文字识别, 图片转文字, 截图识字, 提取图中文字, 扫描识字, 识字, 纯文字,
  plain text extraction, 坐标, 检测框, bbox, bounding box, image to text, screenshot, photo scan,
  recognize text.
license: Apache-2.0
metadata:
  openclaw:
    requires:
      env:
        - PADDLEOCR_ACCESS_TOKEN
      bins:
        - paddleocr
    primaryEnv: PADDLEOCR_ACCESS_TOKEN
    emoji: "🔤"
    install:
      - kind: uv
        package: paddleocr
        bins: [paddleocr]
---

# PaddleOCR Text Recognition

## When to Use This Skill

**Use this skill for**:

- Extract text from images (screenshots, photos, scans)
- Extract text from PDFs or document images when the goal is **line/box-level text**
- Extract text from URLs or local files that point to images/PDFs

**Do not use for**:

- Documents with tables, formulas, charts, or complex layouts — use Document Parsing instead

## Usage

### Basic OCR

From URL:

```bash
paddleocr api \
  --model_type ocr \
  --file_url "https://example.com/image.png"
```

From local file:

```bash
paddleocr api \
  --model_type ocr \
  --file_path "./document.pdf"
```

### Common Options

```bash
# With specific model
paddleocr api \
  --model_type ocr \
  --model PP-OCRv5 \
  --file_path "./report.pdf"

# Disable preprocessing (faster, for flat/well-oriented images)
paddleocr api \
  --model_type ocr \
  --file_path "./document.pdf" \
  --use_doc_unwarping False \
  --use_doc_orientation_classify False

# Save result to file
paddleocr api \
  --model_type ocr \
  --file_url "https://..." \
  --output result.json

# Page ranges
paddleocr api \
  --model_type ocr \
  --file_path "./large.pdf" \
  --page_ranges "1-5,10,15-20"
```

### Output Format

```json
{
  "jobId": "job-xxx",
  "pages": [
    {
      "prunedResult": {
        "rec_texts": ["Line 1", "Line 2"],
        "rec_scores": [0.98, 0.95]
      },
      "ocrImageUrl": "https://..."
    }
  ]
}
```

## Important Notes

**Preprocessing options**: By default, the API enables document preprocessing (unwarping and orientation classification). For flat, well-oriented images (screenshots, properly scanned documents), you can disable preprocessing for faster results:

```bash
paddleocr api --model_type ocr --file_path "./document.pdf" --use_doc_unwarping False --use_doc_orientation_classify False
```

Keep preprocessing enabled when:
- The input is a photo of a curved or folded document
- The document has significant perspective distortion
- Orientation is uncertain (rotated 90/180/270 degrees)

**Display complete results**: Always show the full extracted content to users. Do not truncate with "..." unless content exceeds 10,000 characters. When multiple pages are processed, summarize if needed but provide complete results when explicitly requested.

**Handle errors gracefully**: When the CLI returns an error, inform the user of the specific issue rather than silently failing or falling back to your own vision capabilities. Common errors:
- Authentication: `PADDLEOCR_ACCESS_TOKEN` invalid or missing
- Quota: API rate limit exceeded
- No content detected: Image may be blank or contain no text

## CLI Reference

Run `paddleocr api --help` for all options.

For full documentation, see: [PaddleOCR Official Documentation](https://www.paddleocr.ai/latest/en/version3.x/inference_deployment/serving/paddleocr_official_api/cli.html)
````

## File: README.md
upstream: https://github.com/paddlepaddle/paddleocr/blob/HEAD/README.md

```text

<div align="center">
  <p>
      <img width="800" src="https://raw.githubusercontent.com/cuicheng01/PaddleX_doc_images/main/images/paddleocr/README/Banner.png" alt="Star-history">
  </p>

<h3>Global Leading OCR Toolkit & Document AI Engine</h3>

English | [简体中文](./readme/README_cn.md) | [繁體中文](./readme/README_tcn.md) | [日本語](./readme/README_ja.md) | [한국어](./readme/README_ko.md) | [Français](./readme/README_fr.md) | [Русский](./readme/README_ru.md) | [Español](./readme/README_es.md) | [العربية](./readme/README_ar.md)

<!-- icon -->

[![PyPI Downloads](https://static.pepy.tech/badge/paddleocr)](https://pepy.tech/projects/paddleocr)
[![Used by](https://img.shields.io/badge/Used%20by-6k%2B%20repositories-blue)](https://github.com/PaddlePaddle/PaddleOCR/network/dependents)
![python](https://img.shields.io/badge/python-3.8~3.12-aff.svg)
![os](https://img.shields.io/badge/os-linux%2C%20win%2C%20mac-pink.svg)
![hardware](https://img.shields.io/badge/hardware-cpu%2C%20gpu%2C%20xpu%2C%20npu-yellow.svg)

[![AI Studio](https://img.shields.io/badge/PaddleOCR-_Offiical_Website-1927BA?logo=data:image/png;base64,iVBORw0KGgoAAAANSUhEUgAAAgAAAAIACAMAAADDpiTIAAAABlBMVEU2P+X///+1KuUwAAAHKklEQVR42u3dS5bjOAwEwALvf2fMavZum6IAImI7b2yYSqU+1Zb//gAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAADKCR/+fzly7rD92yVg69xh8zeLwOa5w+ZvFYHtc4ft3ykB++cOm79PAp6YO2z/Ngl4ZO5l+9+yT4QAvLqS748VF33Ylzdvzpl72f6z53YIGJ6SZdPeNHcIwOycaADdLgCSIgAIgCOAACAAykIAEAAEAAFAABCAT+WQuQVgeBqXhXQIQAAYegowLQBpbg3gZGFyAC6vgBQAMREA2/YfDPxyaDQNyTNz+3Zwn5J4ZG7PB2h0kHhi7plPCImmJwkPzO0RMa3OET0i5uGlzHFze0xcu0vE2Dq3J4U2vEPgSaHbFzPNDQAAAAAAAMBNovdw+cP/ny+uaf7w/+eYADy8kE+F4Offdjn6zZXhAXgiA78G4MNNsmnu1Xr7b3mbOL8T5Ja5bw/A35EC2LiWpzt1y9jRugBy30fLg3NvHPvnuZcC2NsCUXA/aRmA89V07Fwgt37uH8deCmBr6N44pP4UgaUATpdA7v/cMbIB8okliY65/SW5HhJ1ehPmM+8edwXgpbu4R88FayR32Y/P7oZZbOx13/Zr//ZHx27bAPnkFoyewYlbAhD3TvBobr95gaUAtr1EdNx1lgI4OcTTuR3z6+FZMEDRcu9ZCuDgGCdyGxMa4EgBRMvcjrkM7NgBZw5c0TwAUWUhZwRXA2xaya65Xa3jO2qYZ8bu2AD5w38tG5V8aZpoGN6Tz0bOfa9bceyWAciTO0jWyO1Tc5cLwJmF/JfPnXVyu3/slgHIg1n79O2O5fZv+1cHV7sC2HYqmUdHysNzX3sVkMcjUK5Gc+dMs28E5bGtm0V3gloBOP9vgZv+4sYn3RUaYFMCol5uN77g6lUApc8pWs69Zn7snS9Z9Q8G0S0AUTVUUTG3A54R1KSvo/diLAv5fKzynZeN6xogC75u93+AtBTA47OlAFSv6qY/vp3DAjD8iv2ZdFYJwKynMhTK1rInPfzaxW81LnvSgFP9KxrATaCLA3DxHpbFX31ZyNm5XRZyXG5bNkAWfP0rcrsUwOgC6NIAzgBcBiqAWwPgLrAGuGBP6jr2sifdfiJ6QQM4Bbw4AK4B3129ZSFn53ZZyA/GyFty27IBFMDFAXAG8PbyLQv5xULGPRl0K3h2AbwcgCZPhs+LD1zLnjS6AN4NwMU/DVFh7LyhASreTbvqrxdr/J4XT4Swz4FrTS+AGJ7bNbwAYkxuWzZAVljHrJfbjb9wviYXwFO/FJ8Vli4vaICsEMFyBbA3tmtsAUS0zG1c/bj4YwsZH2/+Whd0+1Nb+S7IE2sfPw4RL0XmsR8Nqvz7qFngmPHF34EqjP15AAofAkosZKPC/K6FVoeP02Ehi540NG6AK/4pYP3cLgVwXwHkDQ1QcSGb/uF4WwCmfX8u/+4vgLINcMUlQIfcLgXwXAF0+BGkpQDuuJx7/hwgpu//cWVuO3wxJOz/z8297vgYBwaIO3O7Kn+c194578ltywbIgu8fl+Z2lS+APvnLjnOv8hsgSqxjgwL4Ln9LAezaj98tgPzy7ZcC+GQzxrWxXQpgx370dm6/H7v6jaBoso5dY1swAFlwHWvfBf5pxVa93fCtdx64+1dsgCy4joWvAfPX9VoKYMs6Zse9/8Mlvv7LILlhAfKFFdsSutJXAdFkL3qlADJPrXFcXAC5KYaH586jO9mtAch9S3T0GQJ726ZWAE49kjP3rlDJuetdaL/1zeqZY9c7CRz7s0wCUPxienQBnAuAAtAAlxaAAAxfyBQABSAACkAAFIAAKAABUAACMEkKwL170oh7V8ueNLoAjgTAXWAN4BRwcABcA2oABTA4AApAAyiAwQFQABpAAQwOgALQADMWUgCuEmNyu15fSIY3gFPAiwPgFFADKIDBAVAAGkABCIACmBqAUAAaQAHMDUCMWkgBuMWw3K43F5LhDeAU8OIAuAmkARTA4AAoAA2gAARAAUwNgLvAGkABDA6Au8AaoKOJuV0vLSTDG8Ap4MUBcBNIAyiAwQFQABpAAQwOgALQAApAABTA1AC4C6wBOhqb23V+IRneAE4BLw6Aa0ANoAAGB0ABaAAFMDgACkADKAABUABTA+AusAboKATAQs4trjV+IYcfuJYCcA6gAATAQk69dFkKQANYyLkFcLIBFIDLQAVwawDsSRrAEWBwAJwCagAFMDgACkADKIDBAVAAGkABCIACmBoAzwXWAApgcADsSRrg0iNACoACEADXgAIwdCFTACykALgGFIAfl0kBAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAPBv/gN+IH8U6YveYgAAAABJRU5ErkJggg==&labelColor=white)](https://www.paddleocr.com)
[![Ask DeepWiki](https://deepwiki.com/badge.svg)](https://deepwiki.com/PaddlePaddle/PaddleOCR)
[![License](https://img.shields.io/badge/license-Apache_2.0-green)](../LICENSE)
</div>

**PaddleOCR converts PDF documents and images into structured, LLM-ready data (JSON/Markdown) with industry-leading accuracy. With 70k+ Stars and trusted by top-tier projects like Dify, RAGFlow, and Cherry Studio, PaddleOCR is the bedrock for building intelligent RAG and Agentic applications.**

## 🚀 Key Features

### 📄 Intelligent Document Parsing (LLM-Ready)
> *Transforming messy visuals into structured data for the LLM era.*

* **SOTA Document VLM**: Featuring **PaddleOCR-VL-1.6 (0.9B)**, the industry's leading lightweight vision-language model for document parsing. It achieves 96.3% accuracy on OmniDocBench v1.6, leads in text, formula, and table recognition, and shows significantly enhanced capabilities in ancient documents, rare characters, seals, and charts, with structured outputs in **Markdown** and **JSON** formats.
* **Structure-Aware Conversion**: Powered by **PP-StructureV3**, seamlessly convert complex PDFs and images into **Markdown** or **JSON**. Unlike the PaddleOCR-VL series models, it provides more fine-grained coordinate information, including table cell coordinates, text coordinates, and more.
* **Production-Ready Efficiency**: Achieve commercial-grade accuracy with an ultra-small footprint. Outperforms numerous closed-source solutions in public benchmarks while remaining resource-efficient for edge/cloud deployment.

### 🔍 Universal Text Recognition (Scene OCR)
> *The global gold standard for high-speed, multilingual text spotting.*

* **100+ Languages Supported**: Native recognition for a vast global library. **PP-OCRv6** supports 50 languages with a single unified model (Chinese, English, Japanese, and 46 Latin-script languages) — no model switching needed for multilingual documents.
* **Complex Element Mastery**: Beyond standard text recognition, we support **natural scene text spotting** across a wide range of environments, including IDs, street views, books, and industrial components
* **Performance Leap**: PP-OCRv6 achieves **+4.6% detection** and **+5.1% recognition** accuracy over PP-OCRv5, surpassing mainstream Vision-Language Models. 5.2× CPU inference speedup end-to-end.
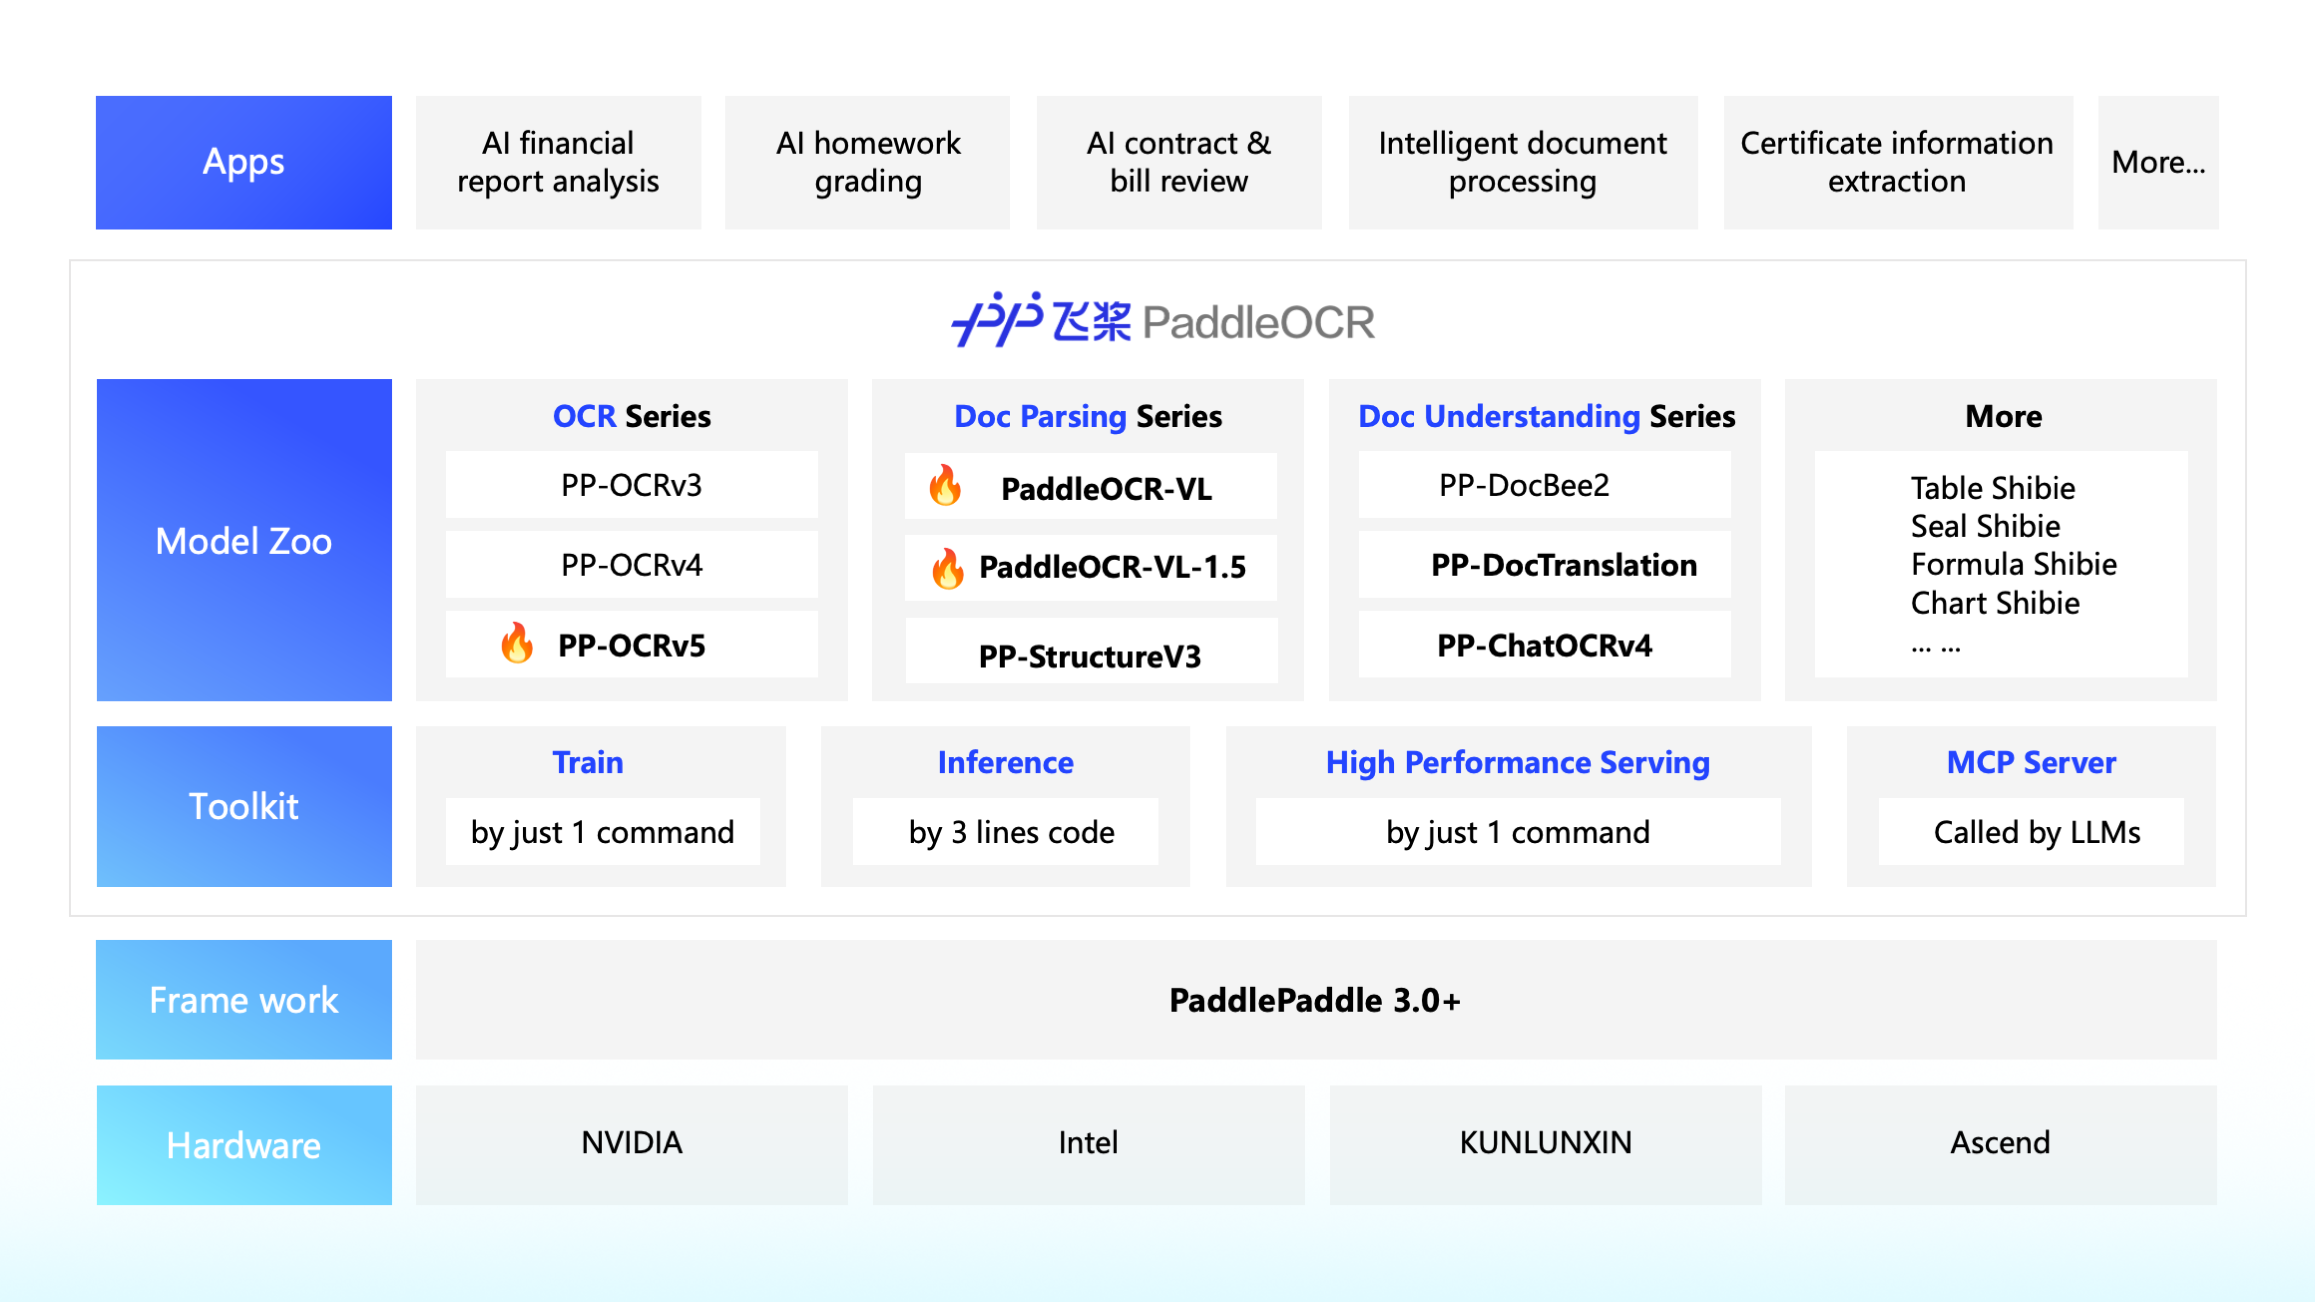
<div align="center">
  <p>
      <img width="100%" src="https://raw.githubusercontent.com/cuicheng01/PaddleX_doc_images/main/images/paddleocr/README/Arch.jpg" alt="PaddleOCR Architecture">
  </p>
</div>

### 🛠️ Developer-Centric Ecosystem
* **Seamless Integration**: The premier choice for the AI Agent ecosystem—deeply integrated with **Dify, RAGFlow, Pathway, and Cherry Studio**.
* **LLM Data Flywheel**: A complete pipeline to build high-quality datasets, providing a sustainable "Data Engine" for fine-tuning Large Language Models.
* **One-Click Deployment**: Supports various hardware backends (NVIDIA GPU, Intel CPU, Kunlunxin XPU, and diverse AI Accelerators).

## 📣 Recent updates

### 🔥 2026.07.22: HPD-Parsing is now available
- **HPD-Parsing** is a lightweight vision-language model designed for high-throughput document parsing. It adopts a hierarchical parallel decoding paradigm and Progressive Multi-Token Prediction (P-MTP), achieving a peak throughput of 4,752 tokens/s on public benchmarks while maintaining competitive parsing accuracy.
- HPD-Parsing supports both OpenAI-compatible serving and local inference through a customized vLLM runtime, making it suitable for document parsing scenarios with high demands on inference efficiency and deployment throughput.
- See the [HPD-Parsing usage tutorial](https://www.paddleocr.ai/latest/en/version3.x/pipeline_usage/HPD-Parsing.html) for environment setup, serving, and local inference instructions.

<details>
<summary><strong>2026.06.11: Release of PaddleOCR 3.7.0</strong></summary>

- PP-OCRv6 highlights:

    - **Accuracy boost**: Medium tier achieves +4.6% detection and +5.1% recognition over PP-OCRv5_server, surpassing mainstream VLMs (Qwen3-VL-235B, GPT-5.5) with only 34.5M parameters.
    - **50 languages unified**: Single model covers Chinese, English, Japanese, and 46 Latin-script languages — no model switching needed.
    - **Specialized scenarios**: Major improvemen
```