⏳ This skill is pending AI review.
Scores will appear once the review pipeline completes.
memecub
Find memes, 表情包 / 斗图 and reaction images and place them into articles, newsletters, docs or video scripts. Use when the user asks to add memes / 表情包 / reaction images to a piece of writing, to "配图" with memes, or to find a meme for a feeling, reaction or character (熊猫头, 奶龙, Drake, This Is Fine…). Searches the memecub library over HTTP with curl; every result says whether it is cleared for commercial use.
Choose how to use this skill
You do not need every option. Choose the path your AI client supports. The stable page stays the same; versioned files are immutable.
1. Native installer
This listing has no registered native installer command. Use the complete package or source fallback below, depending on what your client supports.
Do not guess an installer command or replace an existing version without reviewing the diff.
2. Complete package recommended
Download the ZIP when available. It includes SKILL.md plus the references, security notes and version metadata.
No complete ProSkills package is published for this listing yet.3. Prompt-only
Copy the prompt above when the agent can read the stable page or when you want to adopt the workflow without installing a skill.
Need only the instruction file?
Download SKILL.md only if your client requires a single file. The complete ZIP is safer for a full installation because it preserves the references and release context.
No path installs or executes anything by itself. Your agent still needs access to the project files. Before updating, compare the installed version and review the diff.
// RATINGS
// README
memecub
Meme search and automatic meme placement for AI agents.
Give Claude Code, Cursor, Codex or Claude Desktop a meme library. Search reaction memes by feeling, or hand over an article and get it back with the right meme after the right sentence.
English · 简体中文




Why memecub
- It places memes, not just finds them.
match_articlereads a whole post, picks the sentences worth a meme and returns the article with images inserted. Your agent doesn't have to guess where they go. - Search by feeling. Ask for
facepalm,this is fine,it works on my machine,无语or摸鱼and get the reaction you meant, not a keyword lookalike. - English memes and Chinese 表情包 in one library. Drake, This Is Fine, Doge and Surprised Pikachu next to 熊猫头, 奶龙, 金馆长, 吗喽 and DeepSeek 鲸鱼娘. Chinese queries match whole phrases, so a character name returns that character.
- Zero install. A remote MCP server over Streamable HTTP, or a plain-curl Agent Skill. Searching works without a key.
- License-aware results. Every image says whether it is cleared for commercial use, links its source, and ships a ready Markdown snippet with the credit line when one is required. Ask for commercial-safe only and that's all you get.
- Safe defaults for agents. Memes whose captions contain swearing are left out of agent results unless you ask for them.
Quick start
One command, 40+ agents. Installs the memecub skill into Claude Code, Codex, Cursor, Gemini CLI, GitHub Copilot, OpenClaw, Trae, Windsurf and any other agent that loads Agent Skills:
npx skills add https://memecub.com
Prefer MCP? The server is https://memecub.com/mcp (Streamable HTTP). Pick your client:
Claude Code
claude mcp add --transport http memecub https://memecub.com/mcp
Codex
codex mcp add memecub --url https://memecub.com/mcp
Gemini CLI
gemini mcp add --transport http memecub https://memecub.com/mcp
Cursor (~/.cursor/mcp.json)
{ "mcpServers": { "memecub": { "url": "https://memecub.com/mcp" } } }
VS Code (.vscode/mcp.json)
{ "servers": { "memecub": { "type": "http", "url": "https://memecub.com/mcp" } } }
Claude Desktop / claude.ai: Settings → Connectors → Add custom connector → https://memecub.com/mcp
ChatGPT: Settings → Apps & Connectors → Advanced → turn on developer mode, then create a connector with https://memecub.com/mcp
Cherry Studio, Dify, n8n and other clients that take a remote MCP server work the same way. Step-by-step guides for each tool: memecub.com/developers.
Then just ask:
Add 3 memes to draft.md where they fit.
Find me a facepalm meme, commercial use only.
给这篇文章配几张表情包。
MCP tools
| Tool | What it does |
|---|---|
search_memes | Search by reaction, feeling or character. Filters: commercial_only, no_credit, kind (meme, gif, emoji, artwork, photo), min_size |
match_article | Read an article, pick the spots that deserve a meme, return the article with images inserted (needs a key) |
get_meme | Full details for one image: license, source, author, credit line, tags |
list_categories | Library categories |
You can try it without a key (20 searches a day per IP). Add Authorization: Bearer <key> (run npx memecub login, or create one at memecub.com/dashboard) to use your credits: a free account gets 1,000 a month, a search costs 1 and match_article costs 20 per image it places. Plans and credit packs: memecub.com/pricing.
Agent skill
skills/memecub/SKILL.md teaches an agent to place memes into writing with plain curl. No MCP, no dependencies.
npx skills add https://memecub.com                  # pick your agents interactively
npx skills add https://memecub.com -g -a claude-code  # or target one: codex, cursor, gemini-cli, openclaw…
npx skills add liyupi/memecub                       # same skill, from this repo
memecub.com publishes the skill at /.well-known/agent-skills/index.json, so the site URL is enough.
Or by hand:
# Claude Code: ~/.claude/skills   Codex: ~/.codex/skills   Cursor: ~/.cursor/skills
mkdir -p ~/.claude/skills/memecub
curl -s https://memecub.com/skill.md -o ~/.claude/skills/memecub/SKILL.md
REST API
curl -sG https://memecub.com/api/v1/search --data-urlencode "q=facepalm" -d limit=1
{
"data": [{
"title": "Facepalm",
"url": "https://gpic.code-nav.cn/memecub/public/12vw20qg0awo.jpg",
"page_url": "https://memecub.com/meme/12vw20qg0awo-facepalm",
"width": 679, "height": 600, "kind": "meme",
"license": { "code": "web", "commercial_use": false, "attribution_required": false },
"markdown": "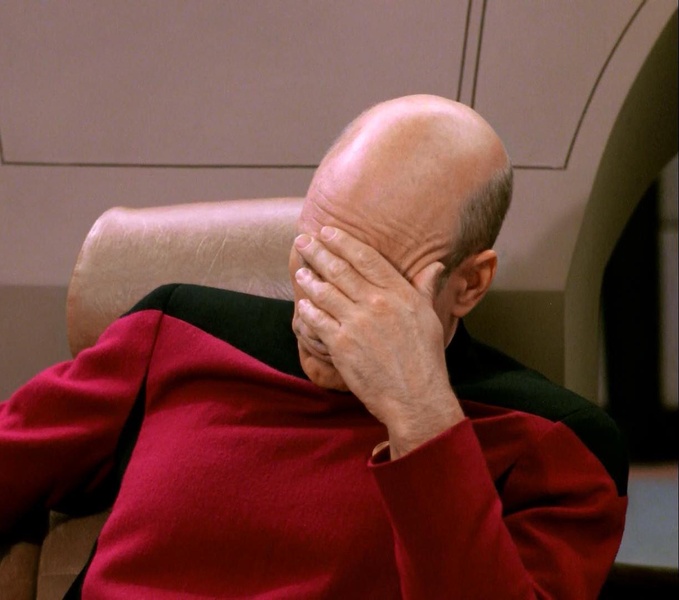"
}]
}
All endpoints and limits: memecub.com/developers.
CLI and JS client
memecub on npm, source in cli/. Node 18+.
npx memecub search "facepalm" --limit 5
npm i -g memecub                                  # or install the `memecub` command
memecub search "facepalm" --limit 5
memecub search "mind blown" --commercial          # only images cleared for commercial use
memecub match ./article.md --count 4 > article.with-memes.md
import { MemecubClient } from "memecub";

const client = new MemecubClient("https://memecub.com", process.env.MEMECUB_API_KEY);
const { data } = await client.search({ q: "mind blown", limit: 5, commercialOnly: true });
The website
Everything the agent sees is also browsable at memecub.com: search, topic pages, one-click copy and download, and the article tool in the browser.
| Home | Topic page | Agent setup |
|---|---|---|
 |  |  |
FAQ
Is it free? Browsing memecub.com is free, and so is light API use: 20 keyless searches a day, or 1,000 credits a month with a free account. Heavier use runs on plans and credit packs.
Can I use the images commercially? Check license.commercial_use on each result. Memes collected from the web are false: copyright belongs to their creators and the source link is kept. Openly licensed images (CC0, public domain, CC BY and similar) are true and come with the credit line when the license needs one. Pass commercial_only: true (MCP) or commercial=1 (REST) to get only those.
// HOW IT'S BUILT
// FILES
2 files shipped with this skill. Inline text is the catalog copy. The upstream link is the source repository.
skills/memecub/SKILL.md6.3 KB6d411d8f734aupstream ↗
--- name: memecub description: Find memes, 表情包 / 斗图 and reaction images and place them into articles, newsletters, docs or video scripts. Use when the user asks to add memes / 表情包 / reaction images to a piece of writing, to "配图" with memes, or to find a meme for a feeling, reaction or character (熊猫头, 奶龙, Drake, This Is Fine…). Searches the memecub library over HTTP with curl; every result says whether it is cleared for commercial use. --- # memecub: memes for writing memecub covers trending memes: Chinese 表情包 / 斗图 (熊猫头, 奶龙, 金馆长, 吗喽…), English reaction memes and templates (Drake, This Is Fine, Doge…), plus openly licensed emoji and art. - Memes collected from the web: `license.commercial_use: false`. - Openly licensed images: `license.commercial_use: true`, with `attribution` (a ready credit line) when `license.attribution_required` is true. Each result has a `markdown` field that already contains the credit line when one is required. ## How to call it Everything goes through one HTTPS endpoint; `curl` is enough. No key is needed to try it (20 searches a day per IP). With a key (`MEMECUB_API_KEY`) each search costs 1 credit from the user's balance (a free account gets 1,000 credits a month) and also covers their private library. The user can get a key with `npx memecub login --print` or at https://memecub.com/dashboard?tab=keys: ```bash curl -sG https://memecub.com/api/v1/search \ --data-urlencode "q=无语" -d limit=8 -d min_size=150 \ ${MEMECUB_API_KEY:+-H "Authorization: Bearer $MEMECUB_API_KEY"} ``` The response is JSON: `{"data": [{id, title, url, width, height, kind, license: {commercial_use, attribution_required, …}, attribution, markdown}, …], "total": …}`. Query parameters: | Parameter | Use | |---|---| | `q` | 1–3 words describing the reaction or character | | `limit` | up to 50 | | `min_size=150` | skip images too small for an article | | `kind=meme` / `kind=gif` | only memes / only animated memes (when emoji or photos crowd the results) | | `commercial=1` | only images cleared for commercial use | | `no_credit=1` | only commercially usable images that need no credit line | | `private=1` | only the user's own uploads (needs a key) | | `profanity=1` | also return memes whose captions contain swearing (hidden by default; only if the user asks) | If a `memecub` MCP server is connected, its `search_memes` tool takes the same options and you can use it instead of curl. ## Placing memes into an article Do the reading yourself; only call memecub for search. This keeps cost low and gives better picks. 1. **Read the whole piece.** Note its language, tone, audience, and whether it is commercial (ads, sponsored posts, client work). 2. **Pick the spots.** Default to one image per 400–600 words (Chinese: per 600–1000 characters), at most one per section, never more than the user asked for. Good spots: a punchline, a surprise or reveal, a pain point the reader recognizes, a win, an ironic aside. Skip the title, the first sentence, code blocks, tables and anything solemn. 3. **Describe each spot as a reaction, not a topic.** Search for what the reader should *feel*. Chinese 表情包 searches work best as short 2–4 character phrases: `无语`, `裂开`, `震惊`, `摸鱼`, `打工人`, `崩溃`, `感动哭了`. English: `facepalm`, `mind blown`, `this is fine`, `side eye`. For a named character (熊猫头, 奶龙, Drake) or the user's own mascot, search the name too. 4. **Search in the article's language first**, 2–3 phrasings per spot, with `min_size=150`. Chinese articles get Chinese 表情包 from Chinese queries; English queries mostly return English memes and emoji, so use them only as a fallback. For commercial pieces add `commercial=1` if the user wants to stay safe. 5. **Choose.** Prefer, in order: matches the reaction precisely; the caption (`title`) fits the sentence; visual variety across the article (don't use the same character twice in a row). Never reuse an image in one article. 6. **Insert** each image on its own line right after the paragraph it reacts to, with a blank line before and after, using the result's `markdown` field unchanged. It already includes the credit line when the license requires one; do not strip it. 7. **Report back** with a short list: where each image went, which image, and whether it is cleared for commercial use. Mention any spot you skipped because nothing fit well. Do not invent images or URLs. ## One-shot alternative If the user has a key and just wants it done server-side: ```bash curl -s -X POST https://memecub.com/api/v1/match \ -H "Authorization: Bearer $MEMECUB_API_KEY" -H "Content-Type: application/json" \ -d '{"text": "<the article, JSON-escaped>", "count": 4, "commercial": false}' ``` The response has `data.markdown` (the article with memes inserted) and `data.slots` (each spot, the chosen meme, alternatives, and `placed: false` if the sentence could not be found). It costs 20 credits per image actually placed (spots it could not fill and failed runs are not charged). Doing the reading yourself and calling search per spot costs 1 credit each, so prefer that. ## Finding a single meme For "find me a meme for X": search 2–3 phrasings, show the top 3–5 as Markdown images with whether each is cleared for commercial use, and let the user choose. ## Rules - Only use images returned by memecub. Never hotlink or suggest images from elsewhere as "free to use". - Keep credit lines whenever `attribution_required` is true. - If the user says the piece is commercial and you used any `commercial_use: false` image, say so once in your report and offer `commercial=1` alternatives. - Images marked `private: true` belong to the user's private library: the user declared they have rights to them. Remind the user once if such an image's declared license is non-commercial (e.g. `cc-by-nc-sa`) and the article looks commercial. - If results are thin, say so and try other phrasings; memecub fetches more images for that query in the background, so retrying in a minute can help. - On HTTP 429 without a key, the keyless daily limit is used up: tell the user to run `npx memecub login --print` (or create a key at https://memecub.com/dashboard?tab=keys) and set `MEMECUB_API_KEY`. On HTTP 402 the user's credits ran out: point them to https://memecub.com/pricing. Do not retry in a loop.README.mdupstream ↗
Contents are not inlined in the catalog. Open the upstream file.
Plain-text copy, no login: /skill-bundles/liyupi-memecub-skills-memecub.md